1. Mastering EXPLAIN (ANALYZE, BUFFERS)
Diagnosing exact disk I/O bottlenecks and memory spills
Optimizing SQL queries without reading execution plans is like debugging without a stack trace. Running `EXPLAIN (ANALYZE, BUFFERS, VERBOSE, FORMAT JSON)` runs the query and outputs actual timing, memory buffer hits, and node types.
When reading the output, focus on 'Buffers: shared hit=128 read=450'. 'Hit' means data was retrieved directly from the RAM buffer pool; 'read' means PostgreSQL had to issue a synchronous disk read. High disk reads directly correlate with latency spikes during traffic bursts.
Golden Tip: Watch out for 'Seq Scan on table_name' on tables with over 50,000 rows. A Sequential Scan forces PostgreSQL to read every raw page from disk into memory.
2. The Equality, Sort, Range (ESR) Indexing Rule
How to order columns in composite B-Trees for maximum index selectivity
When creating a multi-column index, column order matters critically. Follow the ESR rule:
1. Equality columns first (`status = 'ACTIVE'`, `tenant_id = 123`).
2. Sort / Order By columns second (`ORDER BY created_at DESC`).
3. Range filter columns last (`salary BETWEEN 50000 AND 120000` or `created_at >= '2026-01-01'`).
-- BAD: Column order prevents efficient index range traversal
-- CREATE INDEX idx_jobs_bad ON jobs (created_at, status, salary);

-- GOOD: Adheres strictly to the Equality -> Sort -> Range rule
CREATE INDEX CONCURRENTLY idx_jobs_optimal
ON jobs (company_id, status, created_at DESC, salary_min);

-- PARTIAL INDEX: Only indexes rows that are actively queryable
-- Reduces index size from 850MB to 42MB on a 5M row table!
CREATE INDEX CONCURRENTLY idx_jobs_published_active
ON jobs (company_id, created_at DESC)
WHERE status = 'published' AND is_deleted = false;
3. Covering Indexes with the INCLUDE Clause
Achieving Index-Only Scans without table heap access
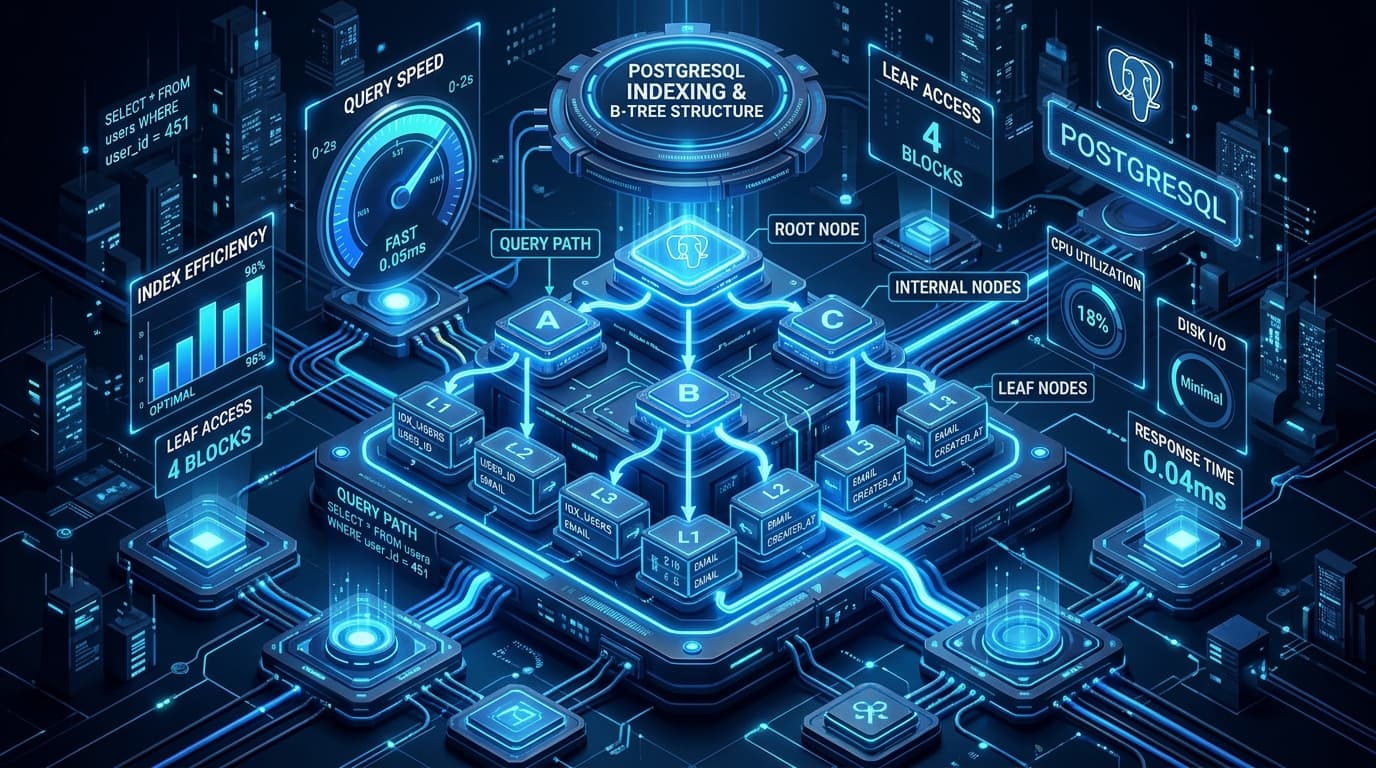
In a standard Index Scan, PostgreSQL traverses the B-Tree to find matching row pointers (TIDs), then fetches the actual table heap page to retrieve non-indexed columns.
By adding the `INCLUDE` clause, secondary columns are stored in the leaf nodes of the index without expanding the B-Tree branching complexity. This allows PostgreSQL to satisfy the entire query via an Index-Only Scan without touching the table heap at all.
-- Satisfies: SELECT title, location, salary_min FROM jobs WHERE company_id = ? ORDER BY created_at DESC
CREATE INDEX CONCURRENTLY idx_jobs_covering
ON jobs (company_id, created_at DESC)
INCLUDE (title, location, salary_min);
4. PgBouncer Connection Pooling & Sizing Formula
Why fewer PostgreSQL database connections mean higher throughput
A common mistake is assigning 500+ direct connections to PostgreSQL. Each PostgreSQL backend process consumes ~10MB RAM and causes context-switching thrashing on Linux CPU cores.
The ideal connection pool size follows PostgreSQL's formula: `connections = (2 * CPU_CORES) + DISK_SPINDLES`. On an 8-core server, 18-25 backend connections running behind PgBouncer in transaction mode can easily handle 5,000+ client requests per second.