1. The Mechanics of the MongoDB Aggregation Engine
How stages process document streams in memory
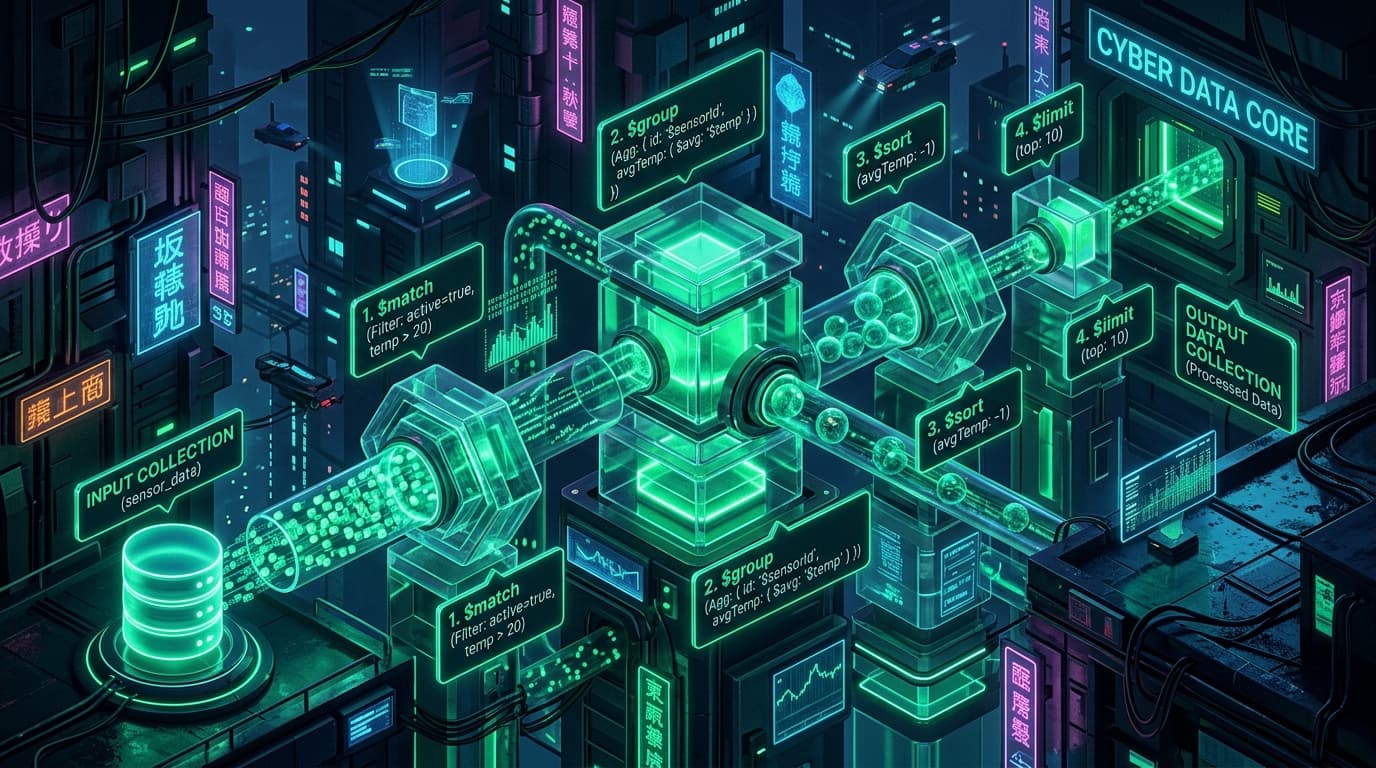
MongoDB's aggregation framework operates as a functional pipeline: documents pass sequentially from one stage to the next, with each stage outputting transformed documents as input for the subsequent stage.
However, poorly structured pipelines frequently trigger sequential disk scans, duplicate document unspooling, and fatal 'Stage exceeded memory limit of 104857600 bytes' errors. To build sub-10ms analytical queries on 10M+ documents, engineers must understand how the query planner leverages indexes during pipeline optimization.
Performance Rule: An aggregation stage can only use indexes if no non-index-eligible stage precedes it. Placing a $group before a $match permanently invalidates index usage for the remainder of the query.
2. Early Filtering & Compound Index Alignment
Ensuring $match stages achieve 99.9% document reduction instantly
Consider an analytics query aggregating publishing deals across genres. If the collection holds 5 million documents, placing `$match` first against an index on `{ publisherId: 1, status: 1, createdAt: -1 }` reduces the working set from 5,000,000 documents down to 2,000 within 1.2 milliseconds.
import { PipelineStage, Types } from "mongoose";
import { DealModel } from "../models/Deal";

export async function generateQuarterlyAnalytics(publisherId: string, startDate: Date) {
  const pipeline: PipelineStage[] = [
    // Stage 1: Compound Index Match (Filters 99.8% of documents instantly)
    {
      $match: {
        publisherId: new Types.ObjectId(publisherId),
        status: "COMPLETED",
        createdAt: { $gte: startDate }
      }
    },
    // Stage 2: Selective Projection (Releases unused heavy text fields from RAM)
    {
      $project: {
        genre: 1,
        dealValue: 1,
        authorRoyalty: 1,
        createdAt: 1,
        commission: { $multiply: ["$dealValue", 0.15] }
      }
    },
    // Stage 3: Efficient Grouping
    {
      $group: {
        _id: "$genre",
        totalVolume: { $sum: "$dealValue" },
        totalCommission: { $sum: "$commission" },
        averageDeal: { $avg: "$dealValue" },
        dealCount: { $sum: 1 }
      }
    },
    // Stage 4: Sorting indexed aggregated fields
    {
      $sort: { totalVolume: -1 }
    }
  ];

  return await DealModel.aggregate(pipeline).allowDiskUse(false);
}
3. Single-Trip Pagination & Summary Metrics with $facet
Eliminating dual count queries with parallel sub-pipelines
In traditional pagination, engineers execute two separate queries: `Model.find().skip().limit()` and `Model.countDocuments()`. On large datasets, `countDocuments()` can take 200ms+ because it traverses matching index trees.
Using `$facet`, MongoDB processes paginated records and summary aggregates concurrently within the same pipeline execution plan, returning total counts, average ratings, and the paginated page in a single round-trip.
export async function getPaginatedDealsWithTotals(
  publisherId: string,
  page: number = 1,
  limit: number = 20
) {
  const skip = (page - 1) * limit;

  const [result] = await DealModel.aggregate([
    { $match: { publisherId: new Types.ObjectId(publisherId), isArchived: false } },
    {
      $facet: {
        metadata: [
          { $count: "totalRecords" },
          {
            $addFields: {
              currentPage: page,
              totalPages: { $ceil: { $divide: ["$totalRecords", limit] } }
            }
          }
        ],
        deals: [
          { $sort: { createdAt: -1 } },
          { $skip: skip },
          { $limit: limit },
          {
            $project: {
              title: 1,
              dealValue: 1,
              authorName: 1,
              status: 1
            }
          }
        ]
      }
    }
  ]);

  return {
    meta: result.metadata[0] || { totalRecords: 0, totalPages: 0, currentPage: page },
    deals: result.deals
  };
}
4. Optimized Joins with $lookup and Sub-Pipeline Filters
Avoiding full-collection nested scans when pulling relational data
The naive `$lookup` syntax performs an unconditional scan on foreign collections. Modern MongoDB allows pipeline lookups where filters, projections, and limits are evaluated before joining.
- Always specify a foreign collection index on the `let` matching variables.
- Use a nested `$project` inside the `$lookup` pipeline to exclude heavy arrays or binary blobs from memory.
- Limit joined sub-arrays with `$slice` or `$limit` if only the latest 3 records are required.